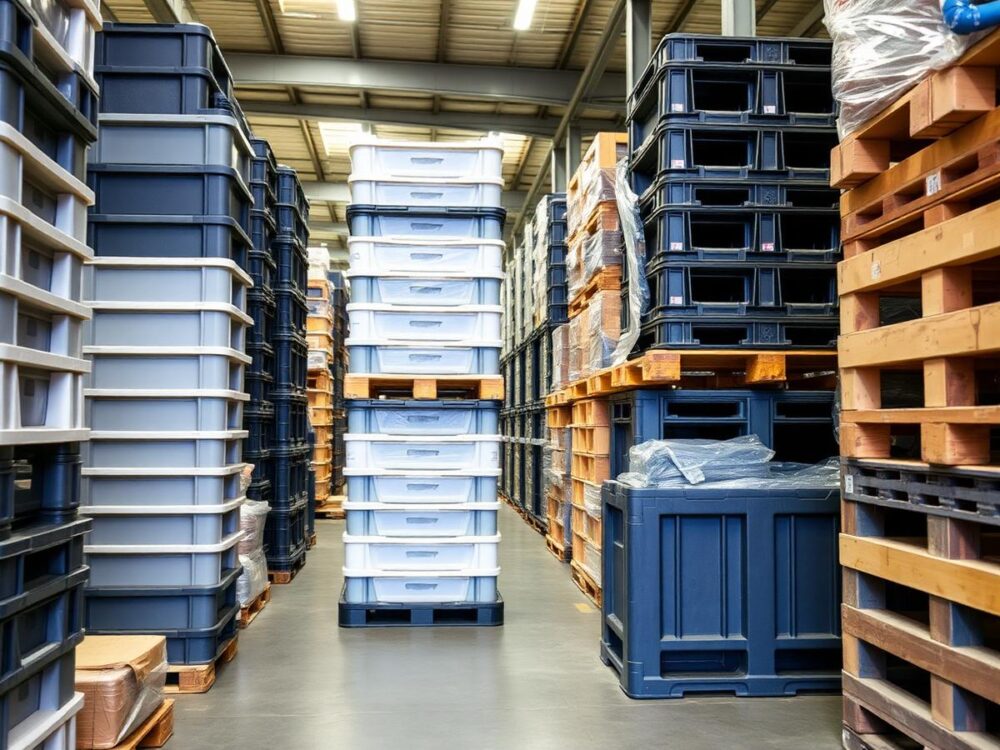
A returnable asset pool can appear short even when the business owns enough equipment. Pallets may be waiting at customers, totes may be held in cleaning, roll cages may be stranded at the wrong depot, and stillages may exist in the asset register but no longer be serviceable. Buying more can hide those problems without solving them.
The opposite failure is equally costly. A pool that is genuinely too small can constrain production, delay deliveries, force emergency rentals or purchases, and weaken the returnable-packaging business case. The right question is not “Which tracker should we buy?” It is “How many serviceable assets must be available, where and when, to meet the agreed service level?”
What counts as a returnable asset pool?
The framework applies to reusable pallets, totes, roll cages, stillages, racks, trays, dollies, IBCs, reusable thermal shippers and other returnable transport items. These assets may circulate inside one company, between plants and distribution centres, or across customers, suppliers, carriers, wash facilities and repair partners.
Before calculating anything, define the pool boundary. State the asset types included, the sites and partners in scope, and the event that starts and ends one cycle. If a cycle begins at issue and ends only when an asset is cleaned, inspected and ready for re-use, do not add the same cleaning time again as a separate allowance. Consistent definitions prevent double counting.
What is the starting equation?
A useful planning relationship is:
BASE CIRCULATION REQUIREMENT = PLANNING DEMAND PER DAY × PLANNING CYCLE TIME IN DAYS
This is an application of the logic behind Little’s Law: the number of items in a stable flow relates to throughput and the average time spent in the system. It is a starting point, not a guarantee. Real returnable networks are seasonal, imbalanced and imperfect, so the base quantity must be adjusted using the operating facts and service objective.
Use planning demand—not necessarily the annual average. A network that must protect a peak month may need a seasonal scenario or a percentile of daily demand. Use planning cycle time—not just the median. A median hides the slow tail, yet that tail often determines whether assets are available during a peak. Segment the calculation by asset type, lane, customer, region or service channel when their flows differ materially.
Which allowances should be added?
| Allowance | Question | Data source | Double-counting caution |
|---|---|---|---|
| Cleaning, inspection, repair or quarantine | How many assets are temporarily unavailable, and for how long? | Maintenance/QMS status, wash records, tracking dwell | Do not add time already included in the defined cycle. |
| Loss and write-off | How many assets disappear or become unrecoverable during supplier replenishment lead time? | Reconciled asset register, recovery cases, write-offs | A “not seen” asset is not automatically lost. |
| Network imbalance | How many serviceable assets are in the wrong place when demand occurs? | Site balances, lane movements, repositioning time | Separate total ownership from location availability. |
| Demand variability and seasonality | What demand pattern must the pool protect? | Orders, production plan, historical peaks | Avoid multiplying both a peak demand and an unexplained safety percentage. |
| Service buffer | What shortage risk will the business accept? | Agreed service objective and scenario model | There is no universal percentage. |
| Replenishment pipeline | How long to source, approve and deploy replacements? | Procurement and supplier records | Count expected losses only across the relevant lead-time horizon. |
Express every allowance in units and show its cause. A single percentage called “contingency” is easy to apply but difficult to challenge. A transparent model lets operations reduce the requirement by shortening a cycle, finance test the cost of a higher service objective, and procurement understand when replacement lead time is creating risk.
How does tracking data improve the calculation?
Tracking contributes observations that are difficult to reconstruct from spreadsheets: dispatch and return timestamps, dwell by site or customer, route and hand-off patterns, last-known location, recovery attempts and repeated slow-return cohorts. With stable asset identities and reliable events, the business can replace a guessed cycle time with a distribution and see where the tail is created.
Tracking is not the only source. Demand normally belongs in ERP, order or production systems. Serviceability belongs in maintenance, quality or asset-management records. Procurement lead time and unit economics belong in purchasing and finance. The model should join those sources through controlled identifiers and clear event definitions.
| Metric | Decision it supports | Likely authority | Caution |
|---|---|---|---|
| Daily demand by asset type and location | Base throughput requirement | ERP/production/order system | Use the planning scenario, not an unlabelled average. |
| Issue-to-ready cycle-time distribution | Base circulation quantity and tail risk | Tracking events plus process records | Missing reads and open cycles can bias the result. |
| Dwell by site, partner and lane | Where process change can release capacity | Tracking/portal/gateway events | Dwell is not automatically avoidable. |
| Serviceable/unavailable state | Which assets can meet demand now | Asset management, maintenance or QMS | A location ping does not prove serviceability. |
| Loss, recovery and write-off | Loss allowance and replacement policy | Reconciled asset register and case workflow | Set a controlled rule for “lost”. |
| Site balance and repositioning time | Imbalance allowance and rebalancing plan | Tracking plus transport plan | A global surplus can coexist with local shortage. |
Should every asset be serialised and tracked?
Not necessarily. High-value, scarce, safety-critical or individually managed assets may justify a unique identifier and whole-pool tracking. A high-volume, lower-value pool may use portal counts, gateway observations or a representative tagged sample to estimate cycle and dwell—provided the sampling method is understood and reconciled.
A sample can help model flow, but it cannot locate every missing unit, prove individual custody or maintain an item-level lifecycle. The technology decision should follow the evidence required: total-flow estimation, individual recovery, automated hand-off, site inventory, serviceability or regulatory traceability. GS1’s Global Returnable Asset Identifier is one standards-based option for identifying returnable assets, including optional serialisation. GS1 EPCIS is one option for exchanging visibility events between applications and organisations. Neither standard decides the commercial case or guarantees event completeness.
Why can averages produce the wrong pool size?
Suppose demand averages 1,000 units per day and average cycle time is six days. The base relationship gives 6,000 units. That answer is only as useful as the assumptions behind it. If one customer keeps assets for 20 days, a repair queue removes 400 units, demand rises sharply each December, or the network cannot move surplus assets between sites quickly enough, 6,000 will not protect the service level.
Model at least three scenarios: normal operation, a representative peak and a credible disruption. Show the central cycle and the slow tail. Make the service buffer a business choice, not a hidden analyst assumption. Where the network is complex, use simulation or cohort analysis rather than forcing every lane into one average.
What data quality checks are essential?
- Stable identity: one physical asset or asset type must not acquire competing identifiers without controlled history.
- Complete event boundary: the model needs a defined issue event and a defined return-to-service event.
- Open-cycle treatment: missing returns, retired assets and late events must not silently distort the cycle distribution.
- Timestamp quality: clock drift, duplicate events, retries and out-of-order messages need explicit handling.
- Observation coverage: missed reads, shielding, dead zones and partner adoption gaps must be measured.
- Lifecycle state: serviceable, cleaning, repair, quarantine, retired and written-off assets must be distinguishable.
- Reconciliation: physical counts, system balances and financial records need a repeatable exception process.
What should an RTI pool-sizing pilot prove?
A pilot should test whether the operating model can estimate the pool and change a decision—not merely show asset locations. Use a representative period and include at least one peak, slow-return cohort or rebalancing problem where practical. Agree acceptance criteria before the pilot.
- The issue and return-to-service boundaries are observable and reconciled with operational records.
- The measured cohort represents the asset types, lanes, partners and seasons used in the decision.
- Duplicates, missed reads, open cycles, late events and asset reassignments have controlled treatment.
- Cycle-time and dwell distributions are reproducible and explainable, not just dashboard averages.
- The model separates circulating, unavailable, lost, retired and misplaced assets.
- A back-test predicts known shortage or surplus periods within a pre-agreed tolerance.
- The team can identify at least one operational lever—faster returns, reduced dwell, improved rebalancing or fewer losses—and compare it with buying more assets.
- The benefits, technology costs, process change and integration effort are visible in the business case.
Buyer decision framework
| Decision | Question to answer before selecting technology | Evidence to request |
|---|---|---|
| Service objective | What demand must be met, where, and with what accepted shortage risk? | Scenario demand, priority rules and named owner. |
| Pool boundary | Which assets, states, sites, partners and events are in scope? | Asset taxonomy, network map and event definitions. |
| Cycle model | What is the full issue-to-ready distribution by relevant cohort? | Complete and open cycles, percentiles and exceptions. |
| Unavailable states | Which units are not ready for use and why? | Cleaning, inspection, repair, quarantine and retirement records. |
| Loss policy | When is an asset missing, recoverable, lost or written off? | Case workflow, ageing rules and reconciled history. |
| Imbalance | Can surplus move to the point of demand in time? | Site balances, repositioning lead time and cost. |
| Technology | Is item identity, site count, gateway detection, positioning or condition evidence required? | Observation design, coverage test and ownership model. |
| Economics | Is it cheaper to buy, recover, repair, reposition or redesign the flow? | Scenario cost model and sensitivity analysis. |
Strategic Tracking Verdict
The best pool-sizing project does not begin with GPS, BLE, RFID, cellular or an RTLS platform. It begins with the service objective and a defensible flow model. Tracking is valuable when it converts unknown cycle time, dwell, imbalance and loss into usable evidence. The biggest capital saving may come from reducing the slow tail or returning idle assets—not from purchasing a different tracker. There is no universal optimum and no universal safety factor. Make the assumptions visible, test them on the real network and keep technology subordinate to the decision.
FAQ
What is the simplest formula for an RTI pool?
Start with planning demand per day multiplied by planning cycle time in days. Then add explicit allowances for unavailable states, loss over replenishment lead time, imbalance, variability and the agreed service buffer. Avoid double counting.
Should I use average or median cycle time?
Neither should be used blindly. Review the full distribution by cohort and choose the planning measure that matches the service objective. A median may hide the slow-return tail; a mean can be distorted by unresolved open cycles.
Can tracking tell me exactly how many pallets or totes to own?
Tracking can improve the evidence for cycle, dwell, location and loss. Demand, serviceability, replenishment lead time, service level and economics come from other business sources. The answer is a cross-functional planning decision.
Do I need to track every returnable asset?
No. Whole-pool serialisation may suit high-value or individually managed assets. Representative samples or portal counts may support flow estimation for high-volume pools, but they cannot recover or prove custody for every individual unit.
How often should the model be recalculated?
Recalculate when demand patterns, cycle time, network design, partners, loss rate, replenishment lead time or service objective changes materially. Monitor leading indicators so the model is challenged before a shortage becomes operational.
Does a location observation prove an asset is available?
No. An asset can be at the right site but in cleaning, repair, quarantine, reserved, damaged or retired. Serviceability must come from the appropriate operational record.
What is the fastest way to reduce required pool size?
Often it is to shorten the issue-to-ready cycle or reduce extreme dwell, but the best lever depends on the network. Compare faster return, rebalancing, repair capacity, loss recovery and purchasing through the same scenario model.
Plan your returnable asset pool-sizing project
Strategic Tracking can help define the pool-sizing problem, audit the available data, compare observation technologies and design a representative pilot before supplier selection. The output is a vendor-neutral decision model: what must be observed, which system owns each fact, how the model will be validated and whether better flow or more assets is the stronger investment.
Explore Industrial Asset Tracking | Review Returnable Packaging Tracking | Plan an independent use-case evaluation
Related guidance: Returnable Asset Tracking Systems & Pallet Pool Management and Visibility Platform Integration Services.